
Scale LLM deployments in real time
Automatically scale models up when demand spikes and down to zero when idle, paying only for what you use.
Sign up by July 31 and get three months free.
Trusted by 2100+ companies globally


Key features
Run self-hosted LLMs without headaches
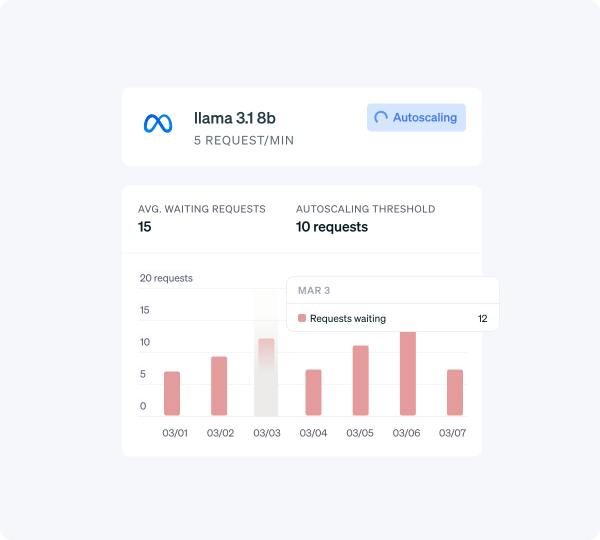
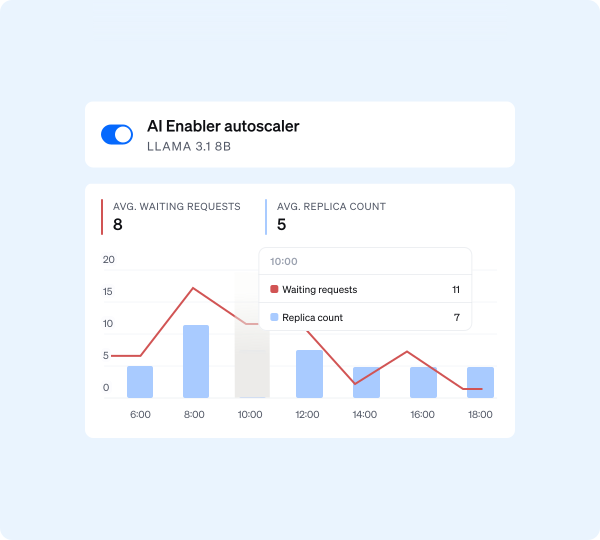
Intelligent model autoscaling
Automatically scale model replicas based on demand—ensuring your users never wait for responses.
- Scaling is fully automated yet deeply configurable to suit your needs
- Maintains optimal response times by scaling replicas before demand peaks
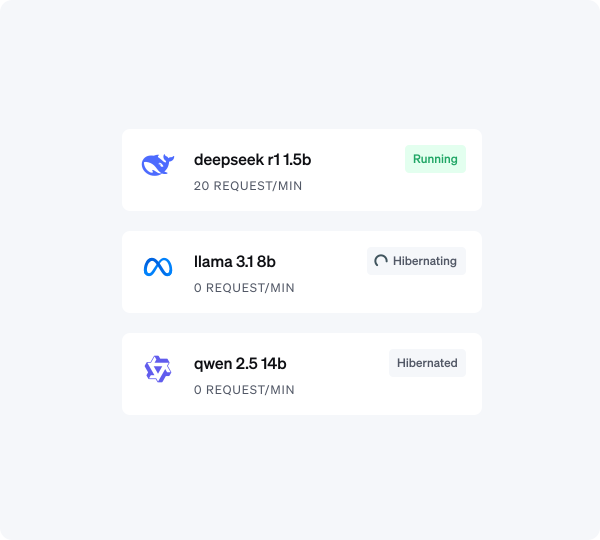
Zero-cost hibernation when idle
Automatically hibernate inactive models and resume instantly when needed—eliminating idle infrastructure costs.
- Hibernation is safe and reversible, preventing any disruption to workloads
- Requests route to fallback models while hibernated models resume, maintaining seamless user experience
Seamless model fallback
Register SaaS providers as fallback—never go offline, never overpay.
- Register SaaS providers as backup options for continuous availability during outages
- Route requests to cheaper APIs during low-traffic periods instead of running self-hosted models inefficiently
Demo video
See how Cast AI can scale LLM deployments in real time
Deploy your own model
Run your LLM on the Cast AI platform to boost resource utilization and reduce cost.
Take advantage of free credits
The Cast router optimizes your queries to maximize free credits from providers.
Prioritize model order
Set a preferred model order to ensure your queries always use the LLMs you prioritize.
Setup
Get started in three steps

Register your LLM provider to let the AI Enabler Proxy route your requests correctly.

Select your provider and run a single script to deploy a lightweight, read-only agent that will analyze your cluster.

Test your configuration in the Playground and see which model delivers the best results at the lowest cost.
Case study
Akamai achieves 40-70% cloud savings, boosts engineer productivity
“I had an aha moment – an iPhone moment – with Cast. Literally two minutes into the integration, we saw the cost analytics, and I had an insight into something I had never had before and had tried to get for a very long time.”

Dekel Shavit
Sr. Director of Engineering
Case study
Yotpo automates Spot Instances, cuts 40% in cloud costs and saves time
“And with Cast AI, we didn’t do anything. Like, we didn’t do the move before, we didn’t do the move after. So there was a lot of human resources and time saved here. That was a very good experience. And again, from a cost perspective, it was highly optimized.”

Achi Solomon
Director of DevOps
Case study
Bede Gaming automatically optimizes K8s workloads with no risk to performance
“In my mind, it’s one less thing to worry about, and therefore teams can be focused on other things of potentially higher value. So having [Cast AI] just run in the background with a good level of confidence that we’re running as efficiently as we can, balancing the service that we’re providing – that’s great.”

Dan Whiteley
Chief Technology Officer
Learn more
Additional resources

Docs
Getting started with LLM optimization solutions for AIOps
Learn how to optimize LLM performance and efficiency with Cast AI’s automated solutions.

Blog
LLM Cost Optimization: How to Run Generative AI Apps Cost-Efficiently
Discover how you can optimize LLM cost without sacrificing performance.

Docs
See the full list of our supported LLM providers
Explore the AI models and cloud platforms compatible with CAST AI’s LLM optimization solutions.
FAQ
Your questions, answered
AI Enabler is a product that lets you to route requests to the best and cheapest Large Language Model (LLM) to make your application cost-efficient.
Using the default LLM or relying on a single provider is not the ideal solution for all of use cases. Teams often end up using more resource-intensive and costly models than necessary, missing out on cost-effective solutions.
With features like a comprehensive cost monitoring dashboard, automatic selection of optimal LLMs (both OSS and commercial), and no additional configuration, AI Enabler significantly reduces costs and operational overhead, making it easier than ever for teams to integrate AI into their applications at a fraction of the price.
Cast AI uses advanced machine learning algorithms to monitor and improve clusters in real time, reducing cloud costs while increasing performance and dependability. The platform includes a Workload Optimization that is optimized for CPU and GPU-intensive applications.
The AI Enabler Proxy integrates with various Large Language Model (LLM) providers, from OpenAI and Anthropic to Mistral and Databricks. Discover all the supported providers on this page.
MLOps or DevOps teams often lack reporting tools that provide real-time information on how much each model costs in terms of compute resources, data utilization, or API calls.
You can use the Playground to compare alternative LLMs and develop benchmarks to identify the best configuration adapted to your requirements. This enables teams to make more informed decisions while also optimizing their LLM usage for optimal efficiency and cost effectiveness.
The solution fully supports both streaming and non-streaming responses.
Can’t find what you’re looking for?

4.8/5 50+ reviews